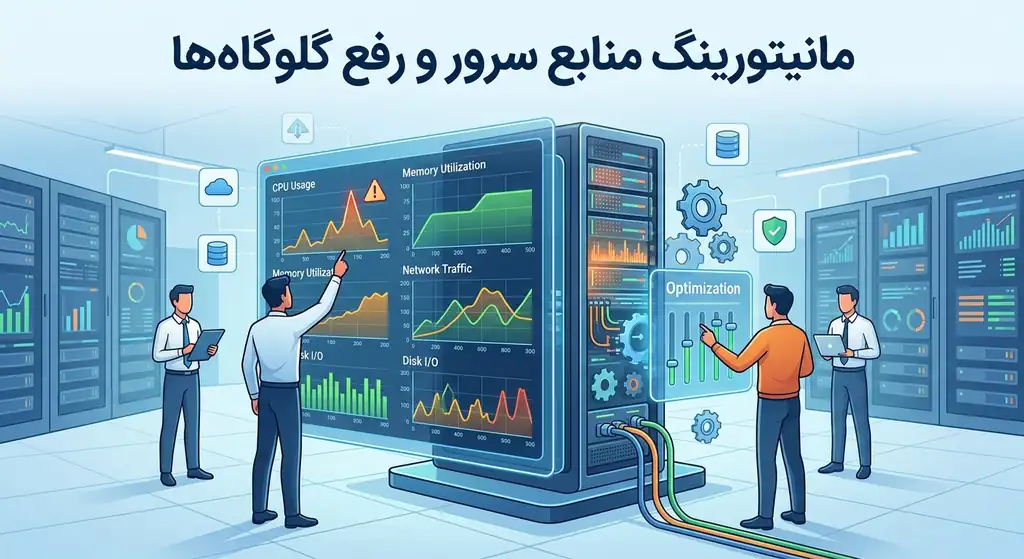
Server monitoring is a critical skill that defines the line between a stable and high-speed service and an unstable and slow service. Without constant resource monitoring, you're walking in the dark and only become aware of a problem when users complain or the site goes down. With the right monitoring, you can identify bottlenecks before they become critical, understand consumption patterns, and make informed decisions about resource optimization. In this practical guide, we examine the tools and methods to identify and fix the bottlenecks of the four main server resources, i.e. CPU, memory, disk and network.
The basic principle in server monitoring is that every bottleneck eventually goes back to one of these four sources. When the site slows down, it's your job to figure out which resource is saturated. A common mistake is to immediately increase RAM or CPU when they see slowness, when the real bottleneck may be elsewhere, such as disk I/O or a specific process.
Four key resources in server monitoring
Before introducing the tools, we need to know what exactly we are monitoring. In server monitoring, there are four main sources, each with its own symptoms and diagnostic tools.
| source | Saturation sign | Diagnostic tool |
|---|---|---|
| CPU | High load average, long execution queue | htop, top, mpstat |
| memory (RAM) | Extreme swap, OOM killer | free, vmstat |
| Disk I/O | High iowait, read/write latency | iostat, iotop |
| Network | Saturation bandwidth, packet drop | iftop, nload, ss |
Knowing these signs will allow you to quickly narrow down the source of the problem. In the following, we will check each one with the appropriate tool.
CPU monitoring and processing bottleneck detection
The first criterion you should check is the system load or load average. This number shows how many processes are waiting to be executed on average. You can quickly see it with the uptime command:
uptime
# 14:32:01 up 40 days,  3:11,  load average: 2.15, 1.98, 1.75
Three numbers show the average load in the last one, five and fifteen minutes, respectively. The key rule is to compare these numbers to the number of CPU cores. If your server has 4 cores and the load average is equal to 4, it means that the CPU is fully busy but without queues. If the load is consistently higher than the number of cores, the CPU is your bottleneck.
Identification of high consumption process
The htop tool provides a live, colorful view of each process's consumption. To see the most consuming processes by CPU:
htop
# یا برای خروجی غیرتعاملی:
ps aux --sort=-%cpu | head -10
If a particular process like php-fpm or mysqld is constantly saturating the CPU, you should optimize at that application level, not just adding cores. For example, MySQL's high CPU usually refers to unoptimized queries, not a lack of CPU.
Important note: a high iowait value in htop (the red part) is a sign that the CPU is waiting for disk, not actually computing. In this case, adding CPU won't help and you have to go for the disk bottleneck.
Memory monitoring and Swap management
RAM memory is another resource that can cripple a server when it is saturated. To view the memory status, use the free command:
free -h
#               total   used   free   shared  buff/cache   available
# Mem:           7.8Gi  4.2Gi  1.1Gi   256Mi      2.5Gi       3.1Gi
# Swap:          2.0Gi  0.5Gi  1.5Gi
The key column is available, not free. Linux uses a portion of RAM for buff/cache that is freed when needed, so less free is not necessarily bad. But if available is very low and Swap is in use, the server is running out of memory.
Extreme risk of OOM Killer and Swap
When it runs out of RAM, the Linux kernel activates a mechanism called the OOM Killer, which kills high-use processes to prevent a complete crash; This can cause the database or web server to crash. To check if OOM Killer is enabled, check the system log:
dmesg | grep -i "killed process"
# یا:
journalctl -k | grep -i oom
Continuous and heavy use of Swap (called swap thrashing) will severely reduce performance because disk is hundreds of times slower than RAM. If vmstat shows that the si and so (swap in/out) columns are constantly high, the server needs more RAM or you should reduce the memory consumption of the applications.
vmstat 2 5Disk monitoring and I/O bottleneck fixing
Disk bottlenecks are one of the most hidden yet common performance problems. A key metric is iowait, which shows the percentage of time the CPU is idle waiting for a disk operation to complete. The iostat tool provides detailed information:
iostat -x 2
# به ستونهای %util و await دقت کنیدThe util% column shows how many percent of the time the disk was busy; Close to 100% means the disk is saturated. The await column is the average waiting time of each request in milliseconds; For SSD disk this number should be below a few milliseconds and for NVMe a fraction of a millisecond. High numbers indicate I/O bottlenecks.
Find the disk consuming process
To find out which process is generating the most I/O, use iotop:
sudo iotop -oPaSolutions for disk bottlenecks include migrating from HDD to SSD or NVMe, adding cache (so that reads are moved to RAM), optimizing database queries that generate a lot of writes, and moving large logs to a separate disk. In many cases, simply enabling the object cache or increasing the database's buffer pool will greatly reduce disk read pressure.
Network and connection monitoring
The fourth source is the network. If the bandwidth becomes saturated or the number of connections exceeds the limit, the server will respond slowly. Use nload or iftop to view live bandwidth consumption:
sudo iftop -i eth0
# مشاهده تعداد اتصالات فعال:
ss -s
The ss command displays a summary of connections. A very high number of connections in the TIME_WAIT state can be a sign of a kernel misconfiguration or a possible attack. To count connections by state:
ss -tan | awk '{print $1}' | sort | uniq -c | sort -rnTrend analysis and capacity measurement
Momentary monitoring is good for crisis response, but the real value of monitoring lies in long-term trend analysis. By looking at several weeks or months of data, you can see growth patterns and plan for upgrades before the server hits the ceiling. This work is called capacity planning.
For example, if you see that the average RAM usage increases by 5% every month, you can estimate how many months you will need to upgrade your RAM. Likewise, identifying periodic patterns such as peak traffic at specific hours or days will help you schedule heavy tasks such as backups or table optimizations during off-peak hours.
Separating the symptom from the cause
One of the key skills in de-bottlenecking is to separate the symptom from the root cause. High CPU usage is a symptom, not a cause. The cause could be a bad query, an infinite loop in the code, or a traffic attack. The correct approach is to move from the symptom to the cause:
- First identify the saturated resource (CPU, RAM, disk or network).
- Then find the process responsible for that consumption.
- Finally, understand why that process consumes so many resources.
For example, if you see iowait above, you'll find the disk-consuming process with iotop, and if that process was mysqld, you'll go to the slow query log to find the culprit query. This logical chain eliminates the guesswork and takes you straight to the solution.
Practical tip: Always record the baseline before making a big change. Without knowing the normal behavior of the server, you cannot tell whether a number is abnormal or normal. For example, a load average of 3 may be normal for one server and alarming for another.
Setting up continuous monitoring and alerting
Command-line tools are great for momentary checks, but for long-term monitoring you need a continuous monitoring system that stores data over time and sends alerts when thresholds are crossed. Some common approaches:
- Netdata: Fast installation and highly accurate live dashboard with every second graphs; Great for a quick start.
- Prometheus + Grafana: Industry standard for metric collection and professional dashboard and alert creation; Suitable for larger environments.
- Monit or Uptime Kuma: for monitoring the availability of services and automatic restart in case of failure.
Installing Netdata is just one command and immediately gives you a complete dashboard:
wget -O /tmp/netdata-kickstart.sh https://get.netdata.cloud/kickstart.sh
sh /tmp/netdata-kickstart.sh
The most important part is setting the alert. You should set thresholds that will notify you before it becomes critical; For example, warning when the disk usage exceeds 80%, or when the load average is more than twice the number of cores. Early warning gives you a chance to act before the service is interrupted.
Once the persistent bottleneck is identified, sometimes the solution really is to upgrade resources. If monitoring shows that the server is constantly reaching the CPU or RAM ceiling, it's time to migrate to a more powerful plan; You can purchase a virtual server with more resources and easy upgradeability and follow the additional guides in Rapido Server Articles.
Monitoring logs and events
Resource monitoring is only half the story; The other half is monitoring system and application logs. Many problems first show up in the logs before they appear in the resource graph. For example, a sudden increase in 500 errors in the Nginx log can be the first sign of a backend problem. You can follow the logs live with the tail command:
tail -f /var/log/nginx/error.log
# شمارش کدهای وضعیت در لاگ دسترسی:
awk '{print $9}' /var/log/nginx/access.log | sort | uniq -c | sort -rn
This command shows the distribution of HTTP status codes. If the number of 404 or 500 errors is unusually high, you should investigate. For larger environments, log centralization tools such as Loki or the ELK stack allow searching and alerting on logs from multiple servers, providing a unified picture of the health of the entire system.
Automate response to problems
Finally, monitoring maturity is when you can react to some problems automatically. For example, if a service fails, tools like systemd can restart it automatically with the Restart=on-failure option. Or if the disk reaches a dangerous threshold, an automated script can clean up old logs. This automation reduces operational pressure and prevents nighttime outages.
In summary, server monitoring is an ongoing activity, not a crisis response. By knowing the four key sources, mastering diagnostic tools, monitoring logs and setting up a continuous alert system, you can identify and fix problems before they affect users and provide a stable and high-speed service.
Frequently asked questions
What load average number is considered dangerous?
This number should be measured against the number of CPU cores. If the server has 4 cores, the load average is about 4, which means full use without queues. Numbers consistently higher than the number of cores (e.g. 8 on a 4-core server) are a sign of processing bottlenecks and queues causing slowness.
What is the difference between free and available in the free command?
free is the amount of RAM that is not used at all, but available is the amount of RAM that is actually available for new applications, including cache memory that is freed when needed. Always pay attention to available; free by itself is not a concern because Linux intentionally uses free RAM for cache.
What does high iowait mean and how can I fix it?
A high iowait means the CPU spends most of its time waiting for a disk response, which is a sign of an I/O bottleneck. Solutions include migrating to SSD or NVMe disk, adding cache to reduce disk reads, and optimizing write-heavy database queries. Adding CPU will not help in this case.
What is the best tool to start monitoring?
For a quick start, Netdata is the best option because it installs with a single command and immediately provides a live and detailed dashboard. For larger environments that require long-term history maintenance and advanced alerts, the combination of Prometheus and Grafana is the industry standard.